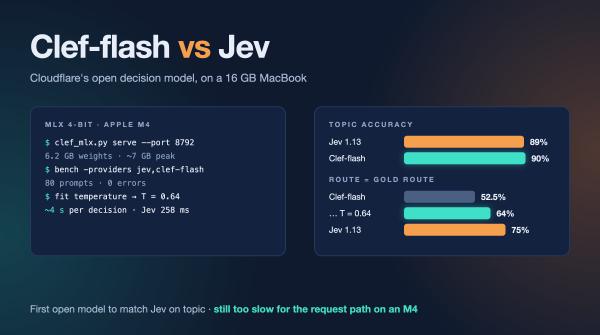
Three days after Cloudflare’s announcement, Clef-flash went through the same 80-prompt benchmark as Jev, Laya, Von and Kev. 90% topic accuracy, a confidence temperature that brings it level with Jev on calibration, and one problem no temperature can fix on a laptop.
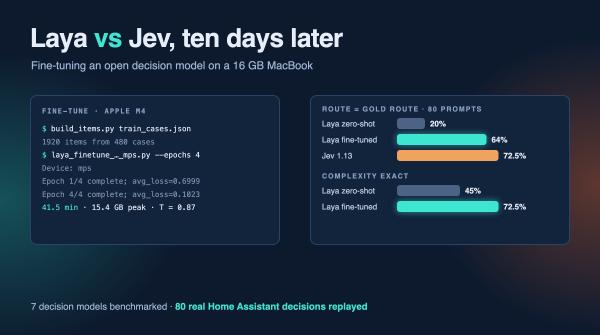
Laya says “fine-tune me”, so I did, on a 16 GB MacBook. Here is the recipe, how long it takes, what it changes on the 80-prompt benchmark, and why my house still runs on Jev.
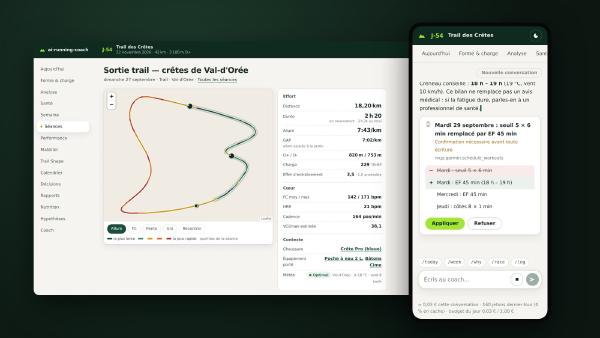
A chat with the coach inside the dashboard, a GPS map on every session, a calorie model that checks Garmin’s numbers, a full gear locker with photo inspections, running dynamics, a second contributor, and “The Trail”, a video series drawn in JavaScript that you can watch right here.
A dashboard, a pile of new metrics, guardrails that can say no, and a coach that lives on a Linux box at home and answers me from my phone. Here is what changed in ai-running-coach since the ultra, and why the automatic sync runs on cron instead of a Claude routine.
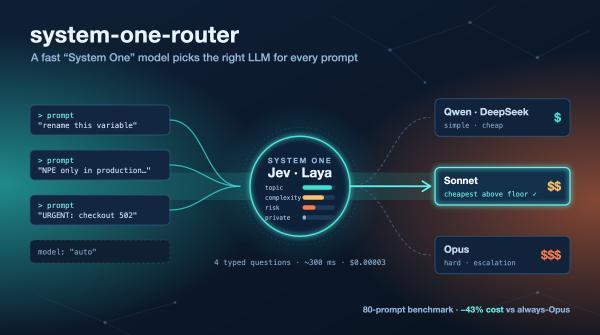
My first model router let an LLM read a prompt file and pick an agent. This one asks a “System One” decision model four typed questions, scores the models with plain arithmetic, and publishes a benchmark to prove it works (and to show where it doesn’t).