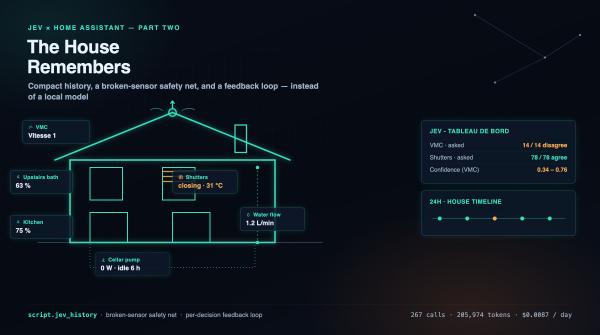
The fix for “Jev has no memory” was never a different model. It was giving Jev a memory. Here is the history script, the feedback loop, and what the live scoreboard already disagrees about.
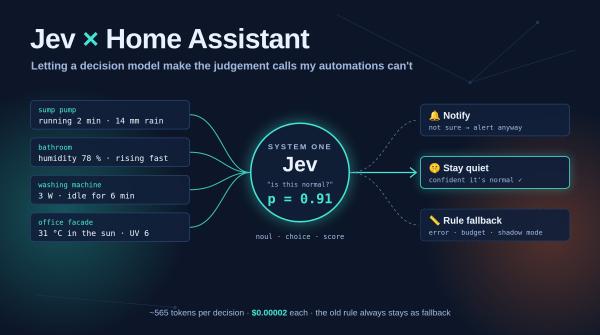
My automations are good at thresholds and bad at context. Jev answers typed questions with a calibrated probability, for about two thousandths of a cent each. Here is how I wired it into Home Assistant with the old rules kept as a safety net, and what it really costs.
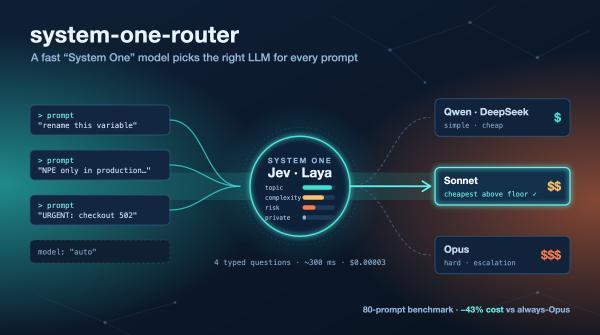
My first model router let an LLM read a prompt file and pick an agent. This one asks a “System One” decision model four typed questions, scores the models with plain arithmetic, and publishes a benchmark to prove it works (and to show where it doesn’t).